Replacing my endless news feed with a twice-daily LLM digest
In May I built a news app that had a local LLM triage every headline and file it under a topic. Four months and 44,000 triaged articles later, I’ve replaced it. It was still an endless feed, only a sorted one, and it was mostly noise. What I’d actually like is something closer to Kagi News: a fixed digest I can finish, where each card is one story, written up from all the outlets that covered it, with highlights, perspectives, angles and a timeline, but with sections that suit me.
The truth is, I didn’t use the old feed much. It was swamped by the news sites, with the same story turning up several times over, because an article gets republished every time its headline is tweaked, and the BBC seems to do that with abandon. A digest asks a different question: “what are the best twelve of today’s few hundred?”
The pipeline
ingest → triage → cluster → rank → synthesise → publish
Ingest. Feed polling is now the job of Miniflux, a small self-hosted RSS reader with a clean API. The digest drains it from a cursor, and merges in Hacker News from Algolia, because HN’s RSS has no scores. I started with 55 feeds and I’m now at 77.
Triage. Everything new gets a section and a score from 0 to 10, from Qwen3.5 on the homelab’s llama-server, 25 articles per call. The reader profile I’d tuned for the old app carried over almost unchanged.
Cluster. This groups together the coverage of each story, and more on it below.
Rank. One comparative call per section fills that section’s quota of slots, so the busiest section can’t swamp the rest.
Synthesise. One call per story, with each source passed in its own words. I’d planned to boil each article down to neutral bullets first, but perspectives are precisely where outlets differ in framing, and neutral bullets are designed to strip framing out. Twelve real clusters took 164 seconds, fetching included, and every one fitted in a single call.
Clustering, and a threshold I measured instead of guessing
Clustering carries more weight than it sounds. With no clusters, there are no perspectives. It also has to happen between triage and ranking, not after them: three outlets covering one story are three candidates to an unclustered ranker, and World only has a handful of slots.
Each article’s title and summary is turned into an embedding (a vector that captures roughly what the text is about) with bge-small-en-v1.5, on the CPU so it never competes with the voice assistant for the GPU. About 450 entries take 12 seconds. Two articles belong together if the cosine similarity between their vectors is high enough. I’d guessed 0.85 for “high enough”. Then I measured some real pairs:
| Pair | Titles only | Title + summary |
|---|---|---|
| Debian 13.7 vs GCC 13.5 (unrelated, same boilerplate) | 0.799 | 0.682 |
| Assisted dying, two outlets | 0.877 | 0.879 |
| Saudi pipeline, FT vs Guardian | — | 0.872 |
| Reform’s £36m donation, five outlets | — | 0.90–0.95 |
Adding the summary is what makes it work: it pushes the false pair right down, while the genuine pairs stay put. Across 452 real scored entries, every pair from 0.84 upwards was the same story, so 0.84 it is. The grouping is anchored too: a newcomer is compared only with each cluster’s first member, never with any member. Otherwise it chains: Reform donations are a bit like Trump, and Trump is a bit like Ireland, and suddenly they’re all one story.
That still didn’t stop an evening digest from gluing together stories that had nothing to do with each other. One card about a ransomware sentencing turned up with an Industrial Revolution paper attached, and the model dutifully wrote a headline joining the two. The threshold was innocent. Each run rebuilt the clusters, but entries outside the time window kept yesterday’s cluster ID, and SQLite happily handed those IDs out again to brand-new clusters. There were 186 of these ghost members, spread across 151 clusters. Every run now clears all the old memberships first.
Not showing me the same thing twice
There’s a lunchtime digest (5 cards: UK, World, and AI & models), a fuller evening one, and a weekend morning one. The rule for repeats is keyed on whether I opened a digest, not on whether it was built:
- If I opened lunchtime’s, the evening digest leaves those stories out, unless one of them has picked up two or more new outlets, in which case it comes back marked developing.
- If I never opened it, its cards move across unchanged, marked carried from lunchtime. A digest should never withhold a story because it offered it once to an empty room.
Opening a digest marks the whole thing read, so there’s no “mark all as read” button. A separate river holds the thirty or so candidates that just missed out. It ends, so it can’t turn back into the firehose.
Sections from the click data
The sections were rebuilt from what I’d actually read in the old app, rather than what I imagined I read. A couple of the old topics went altogether, and so did Other: in a digest, anything that fits no section doesn’t make the cut. And one new section covers something the old sources never touched at all.
The click-throughs were more telling than the reactions. Hacker News stories got read far more often than the newspapers’ ones did. After the first weekend I also widened the digest a little, because good stories in the busier sections were being squeezed out.
Feedback is deliberately weak for now: my reactions go into the triage prompt as examples, and a feed’s score can move by at most one point. With this little data, anything bolder would just be fitting noise.
Where it’s at
The digest has taken over the old app’s address and its PWA shell, and the old container is gone. There’s a long-form tab and a film-and-TV watchlist on the side, which probably deserve a post of their own. As of today it builds on the laptop and ships as an image, like everything else.
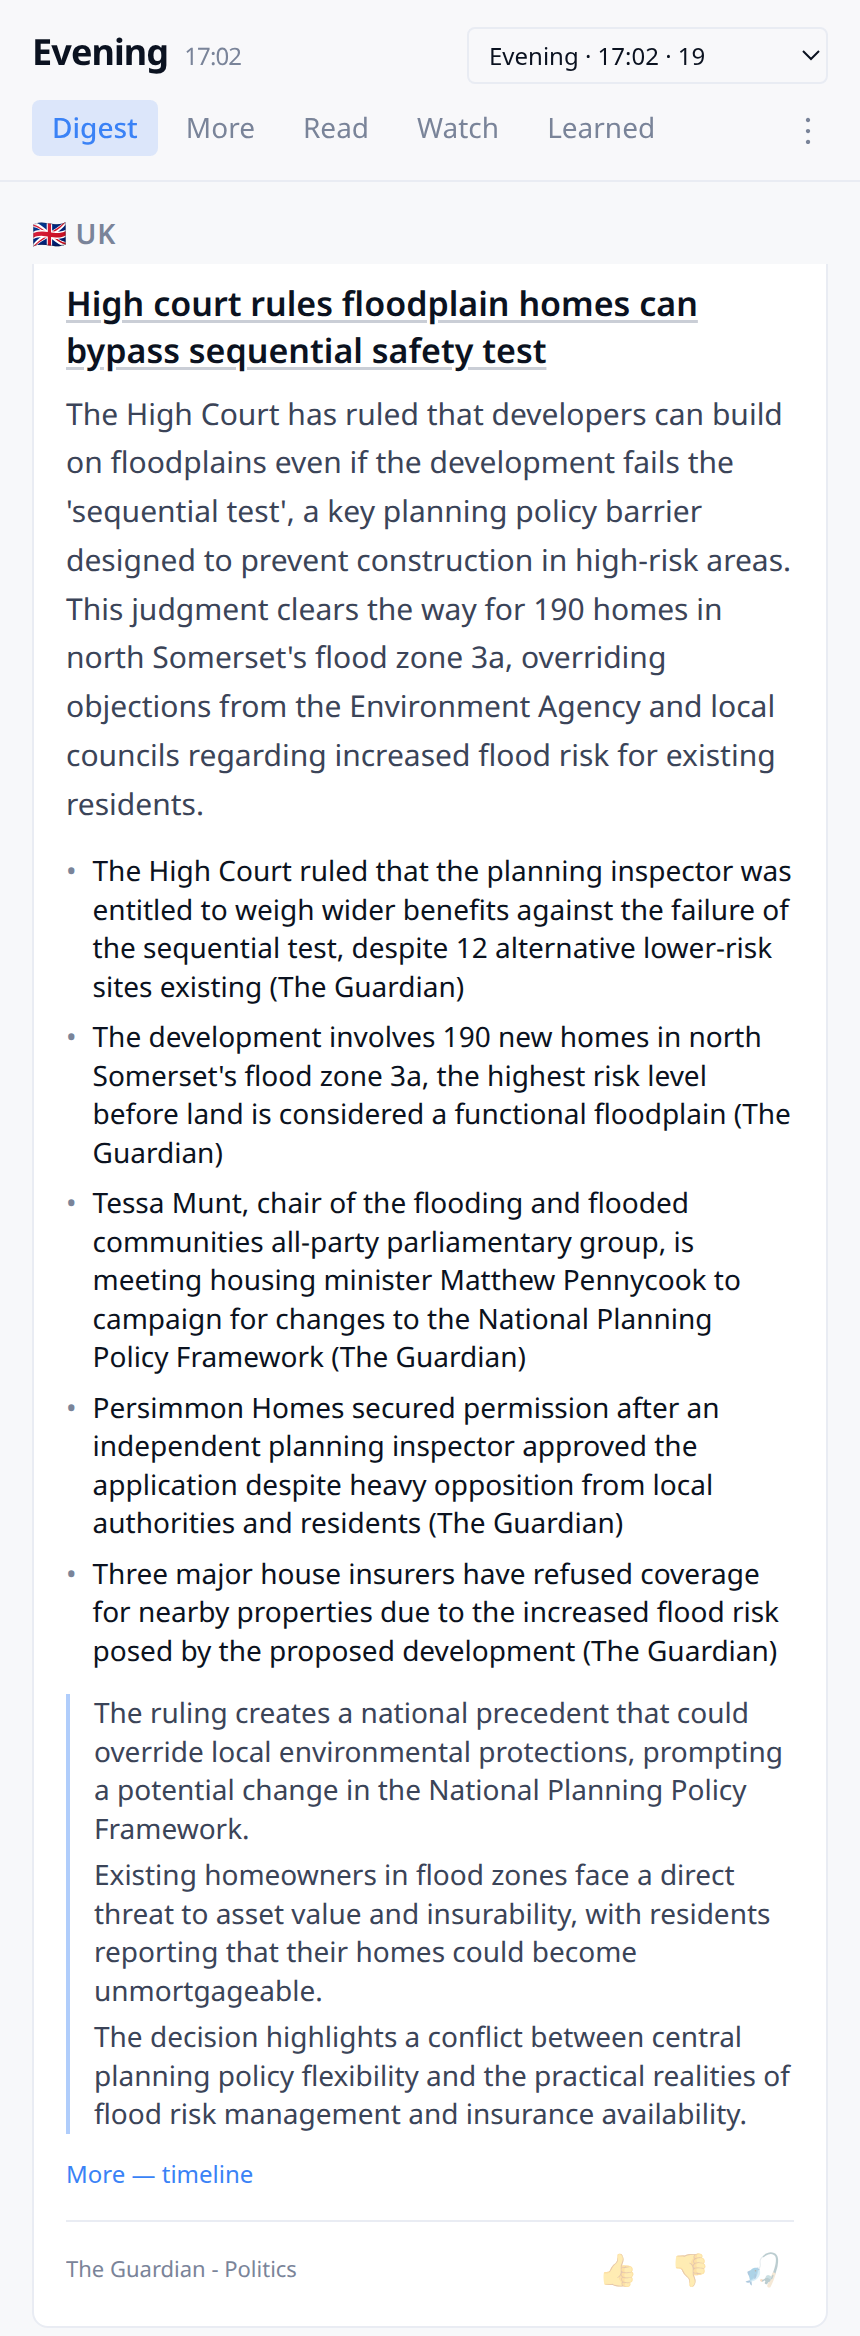
Here’s a card from an evening digest, on a phone, with the story photo turned off. There’s the headline, a written-up summary, the highlights with their sources, and the perspectives underneath:
Project assisted by Claude Code.